Problem
Resizing one image for several networks takes several tools, and uploading private screenshots to unknown sites is a poor trade.
LiveMedia utility1-minute read
Resize, convert and tidy images in the browser; the file never leaves the device.
01
Resizing one image for several networks takes several tools, and uploading private screenshots to unknown sites is a poor trade.
02
Images are converted, resized, cropped, optimised and stripped of metadata entirely inside the browser. Social-media links are inspected only through each platform's own public interfaces: nothing is scraped and no protection is circumvented.
03
Everything: what to build and what to refuse, interface, the hardened link service, tests, server and deployment.
Image work for social media without uploading files, with location metadata removed by default.
Live public tool. It does not download video or audio, and nothing is scraped.
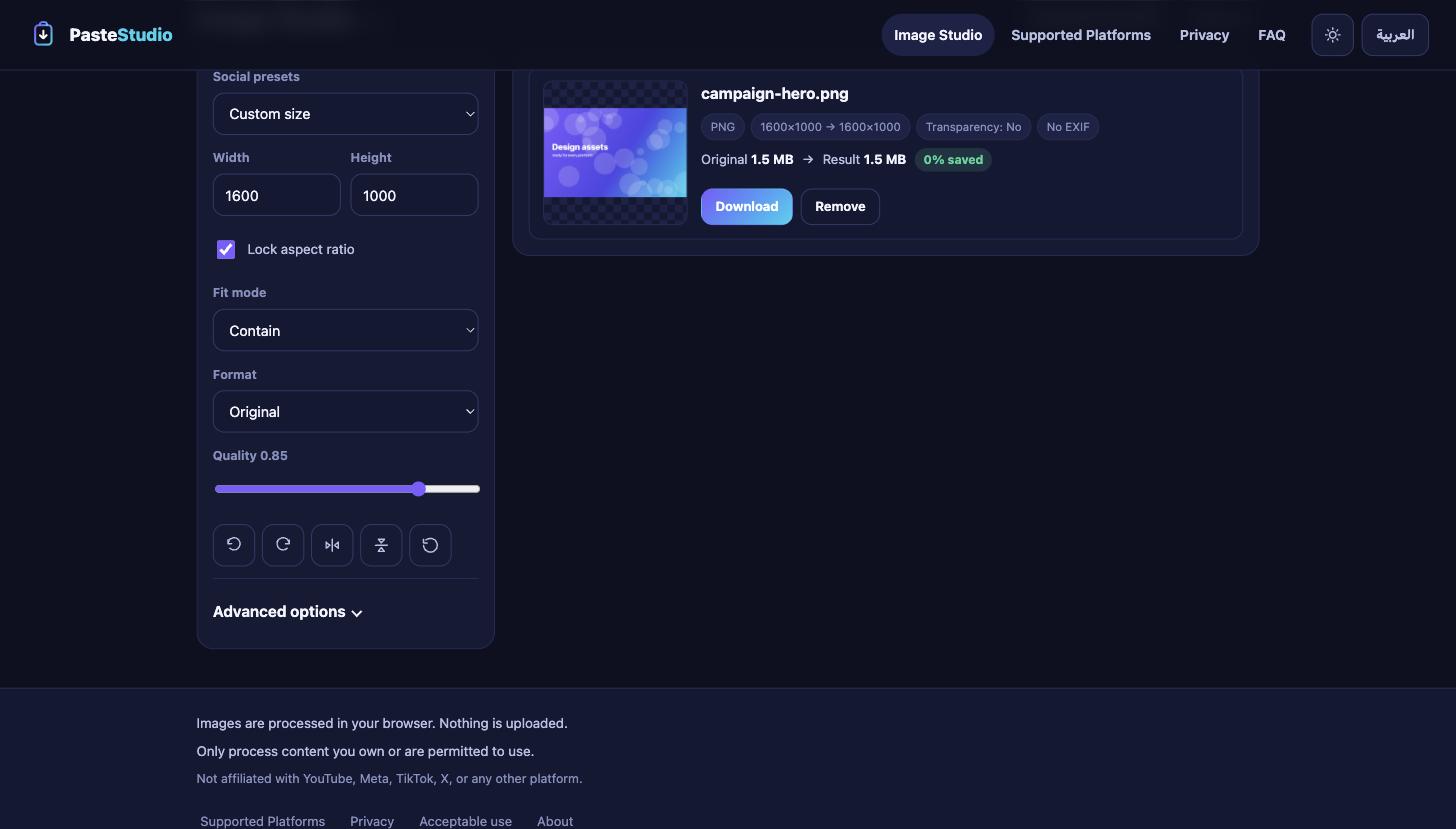
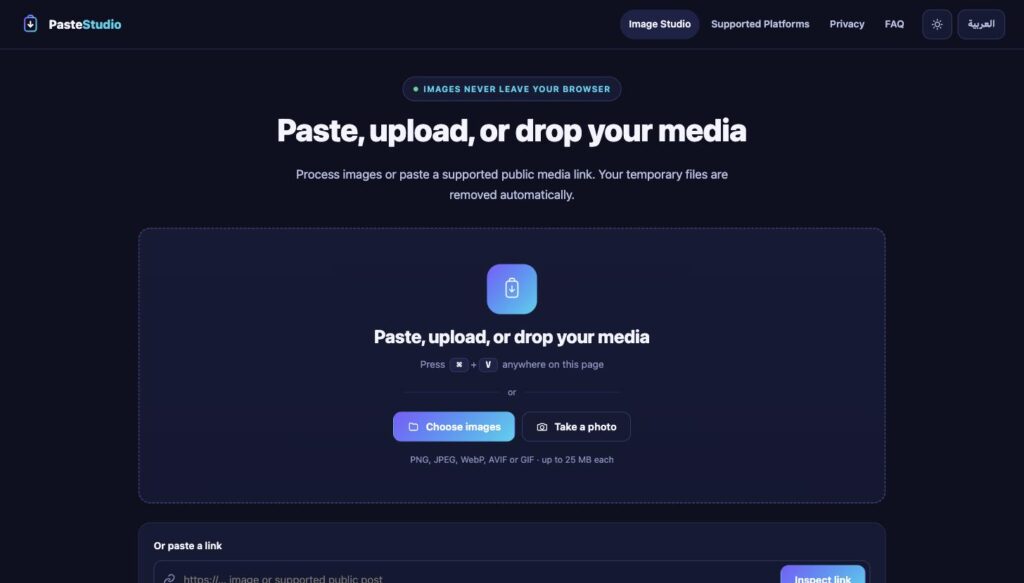
Paste Studio turns a clipboard image into a finished file in as few steps as possible, and tells the truth about what it can do with a social-media link. Images are converted, resized, cropped, optimised and stripped of metadata entirely inside the browser. Links are inspected through each platform’s own public interfaces — nothing is scraped and no protection is circumvented.
Everything: the product decision about what to build and what to refuse, the brand and interface, the Arabic and English content, the client-side image engine, the SSRF-hardened link service, the test suites, the server configuration, and the deployment.
The original brief asked for YouTube and social-media downloads. Building that means using a tool like yt-dlp, which works by deciphering YouTube’s signature and throttling parameters. That is circumventing a technical protection measure, and it breaks terms that bind the operator of the service — a checkbox from a visitor cannot waive them.
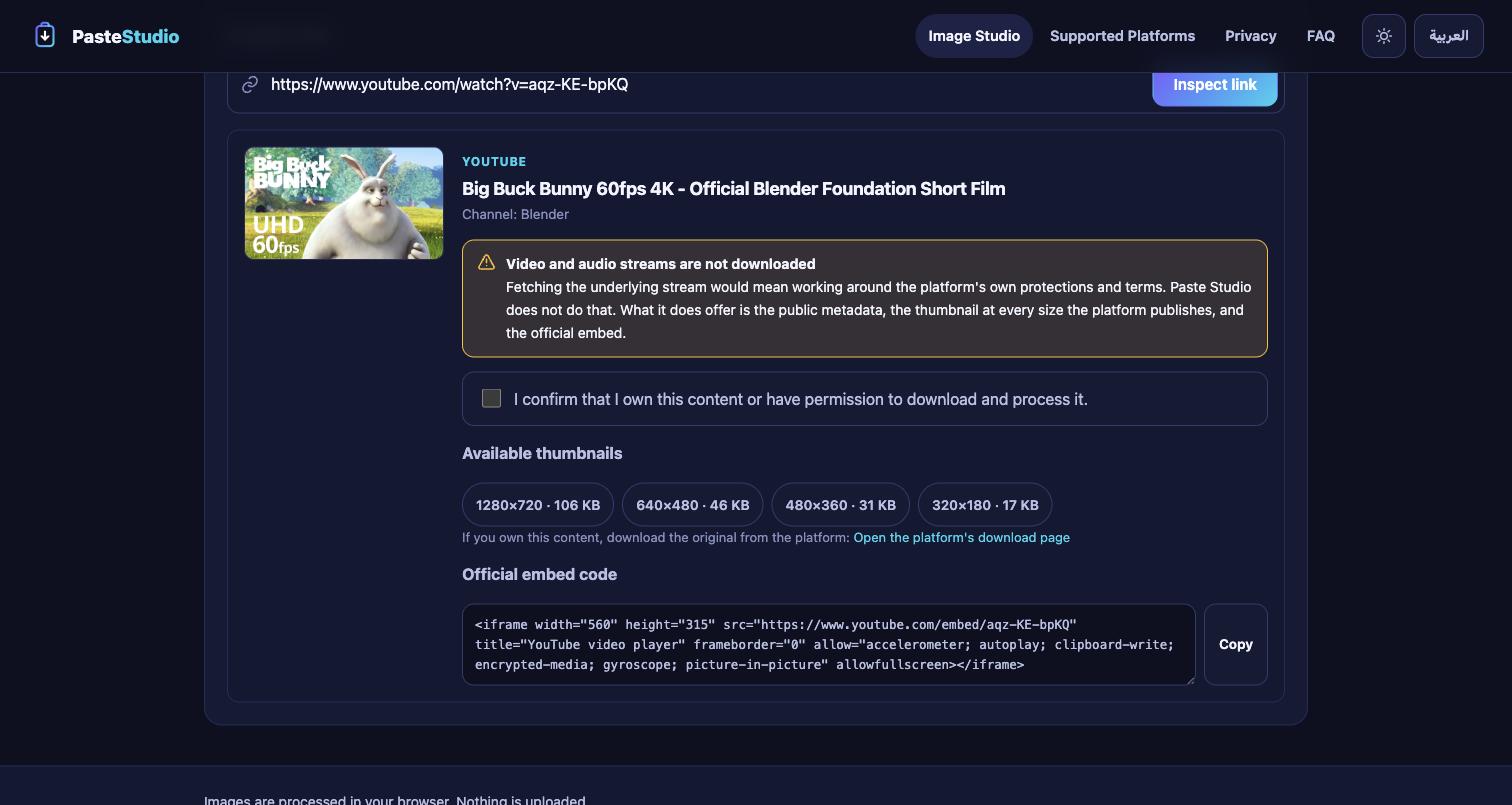
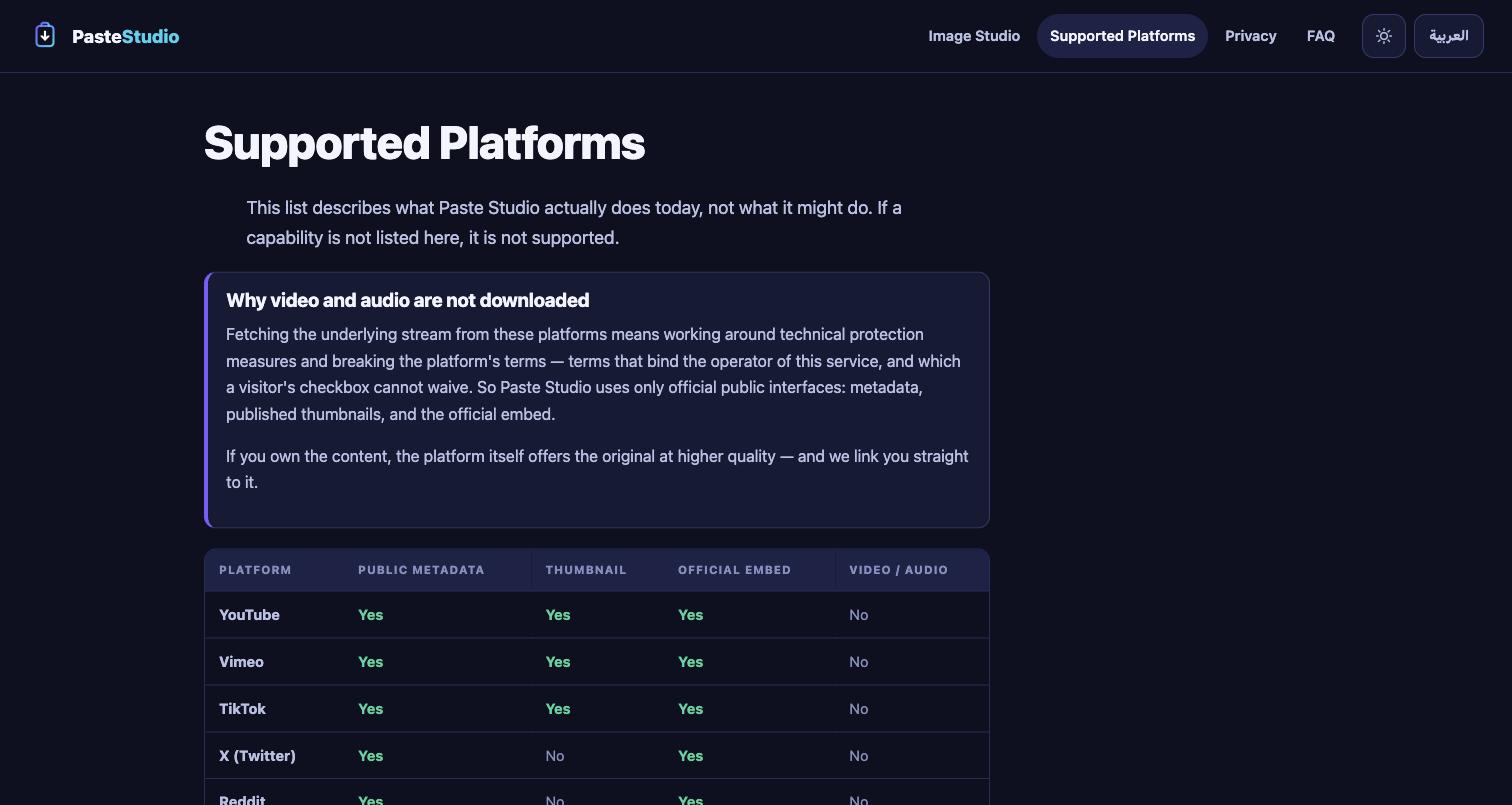
So Paste Studio does not download video or audio streams. Instead it uses each platform’s own public oEmbed endpoint for metadata, relays the thumbnails they already publish as ordinary images, offers the official embed code, and points content owners at the platform’s own download. The Supported Platforms page states this in a table rather than burying it.
That constraint turned out to be the product’s strength. With no media pipeline there is no job queue, no temporary media on disk, no cleanup to get wrong, and no retention question to answer carefully — because nothing is retained.
Nothing downloads automatically on paste. The preview comes first and the visitor decides.

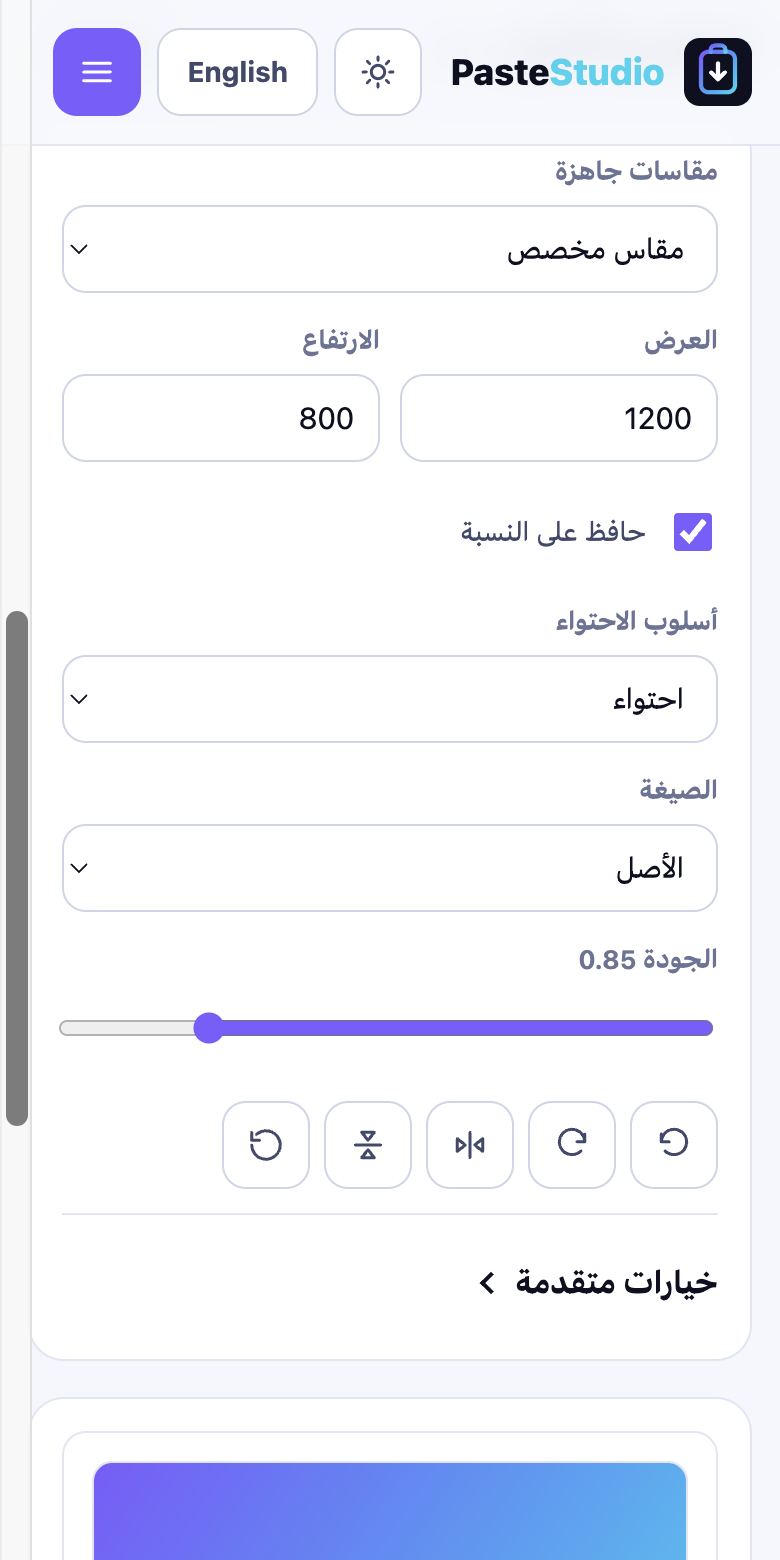
All of this runs on a canvas in the visitor’s browser. There is no upload, no queue and no server round trip.
Eleven platforms are recognised. For each, the capability table lists what is genuinely available: metadata, thumbnail, official embed — and, in every case, no video or audio.

For YouTube the video id is parsed locally and the four published thumbnail sizes are probed directly against the official image host, so the list shows only sizes that really exist, with their real byte sizes. Choosing one requires an explicit, unchecked rights confirmation, and the thumbnail then opens in the Image Studio like any other image.

The link service is the only part that talks to the internet, so it is the only part that can be turned against the server. The attack to defend is Server-Side Request Forgery: persuading this machine to fetch something only it can reach — localhost, the private network, or the cloud metadata endpoint that hands out credentials.
A hostname allowlist alone does not stop that. evil.com can resolve to 169.254.169.254, and a name that resolves safely during validation can resolve elsewhere moments later when the HTTP client looks it up again — DNS rebinding. So the fetcher does three things a naive one does not:
The security claims above are assertions in a suite, not adjectives. Among the cases: the AWS and GCP metadata endpoints, localhost, 127.0.0.1, [::1], every private IPv4 range, IPv6 unique-local and link-local, IPv4-mapped IPv6 forms of private addresses, NAT64-wrapped loopback, file://, gopher://, a suffix-confusion host (youtube.com.attacker.example), credentials embedded in the URL, a non-standard port, and a malformed video id.
| Suite | Covers | Assertions |
|---|---|---|
| Unit | Address classification, host allowlist, URL validation, platform detection, YouTube id parsing, capability honesty, bilingual parity | 139 |
| Live HTTP | Both language trees, metadata and assets, security headers, path exposure, link API, SSRF refusals, thumbnail relay, rate limiting, copy honesty | 105 |
The image engine was verified in a real browser: a PNG with genuine alpha, conversion to JPEG and WebP at several qualities, a JPEG carrying a hand-built EXIF APP1 block — confirmed present on input and confirmed absent from the exported bytes — batch processing of differently sized files, and a ZIP whose entries were extracted and decoded back into images.
The privacy page does not say “nothing is stored”, because a web server keeps an access log and that would be untrue. What it says is narrower and verifiable: images never reach the server at all.
Each language has its own URL — /privacy and /ar/privacy — rather than a client-side toggle, so both are separately indexable and hreflang means something. The locale is a property of the path, never a cookie, which keeps pages cacheable.


PHP 8.3 rendering both language trees, a tiny JSON API, and vanilla JavaScript doing the image work. No framework, no build step, no package manager, no runtime dependencies.
One bug worth recording: the worker originally matched cached assets with ignoreSearch: true, which quietly defeated the mtime-based cache busting — a new build produced a new URL and the worker served the old body anyway. Matching the full URL fixed it.
Figures from the build itself. There are no user numbers or download counts here, because this is a portfolio demo and has none.